Experimental design
Open the Plan a fair seed experiment room
This article opens a matching guided lab. Follow the on-screen prompts, make a prediction, and connect the model result back to this topic.
01 // What experimental design covers
Experimental design is the overall plan for how an experiment will be run, decided before any data is collected. It covers which variables to change and measure, what to hold constant, how many trials to run, and how to keep bias from creeping into the results — get this planning stage wrong, and no amount of careful measuring afterward can fix it.
02 // The core decisions
1. Define the variables
Decide exactly what you'll change (independent) and exactly what you'll measure (dependent).
2. Plan the controls
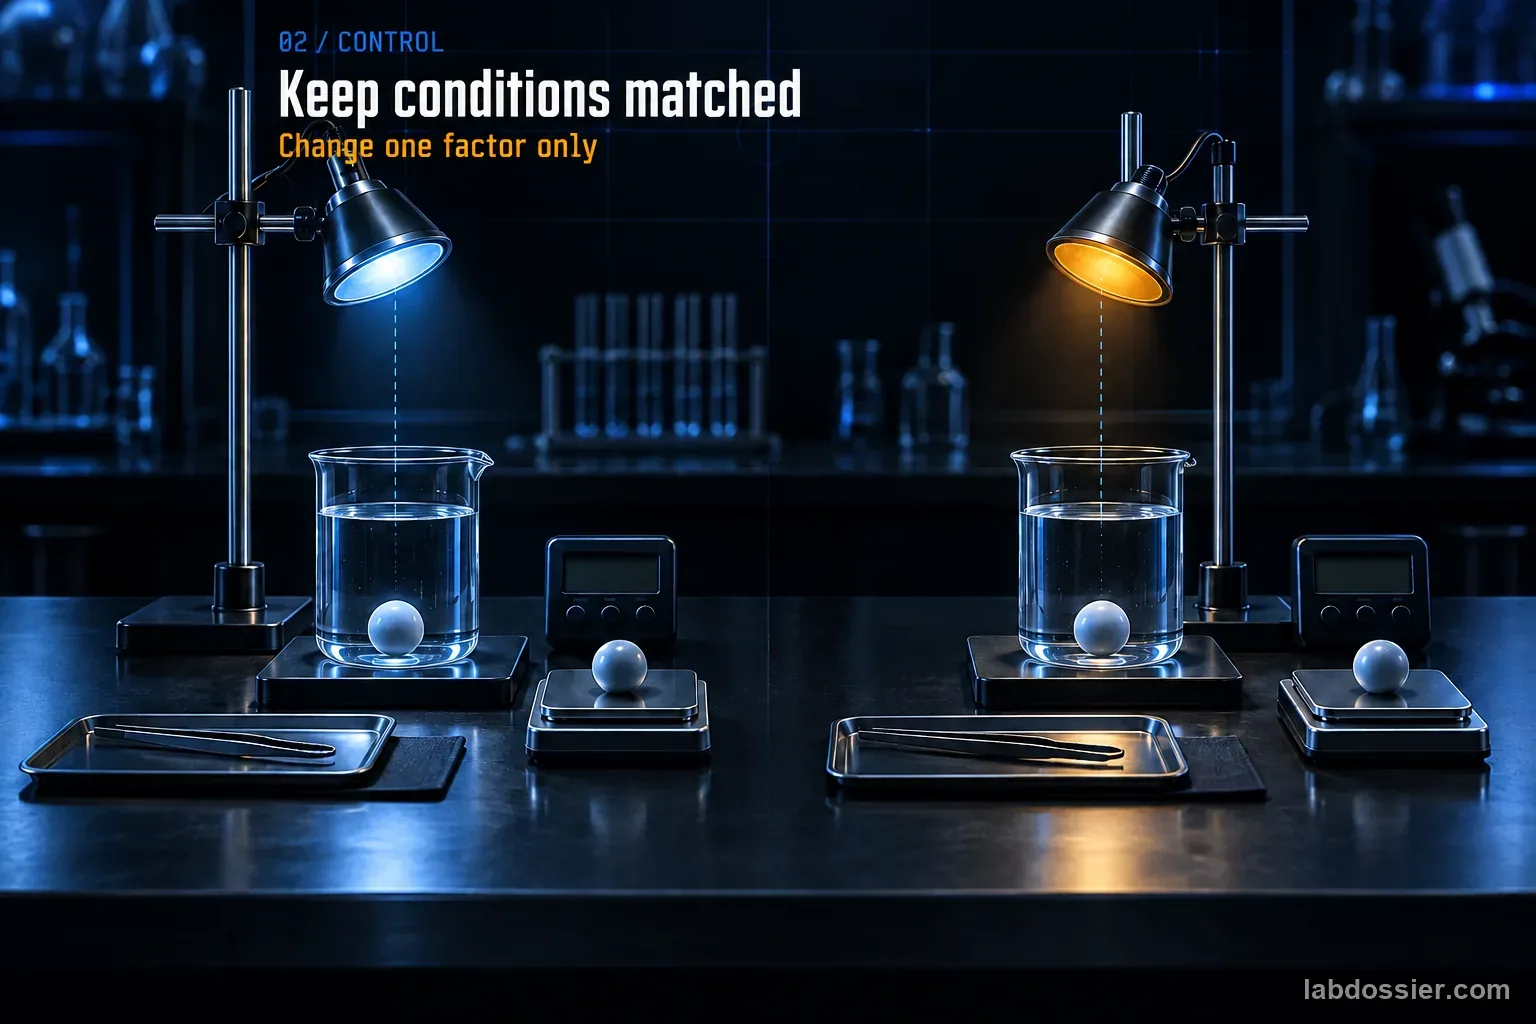
List everything else that needs to stay identical across every group so it can't become a confounding variable.
3. Set up a control group
Include a baseline group that doesn't receive the treatment, to compare against.
4. Decide on sample size and trials
Plan enough subjects or repeated trials that a single unusual result won't distort the conclusion.
5. Reduce bias
Decide how subjects or samples will be assigned to groups — randomly, whenever possible — to avoid stacking one group unfairly.
03 // Common design flaws
- Too few trials makes it hard to tell a real pattern apart from random chance — one or two data points can look like a trend that isn't really there.
- No control group means there's nothing to compare the treatment group against, so there's no baseline to know whether the treatment actually changed anything.
- Non-random group assignment can accidentally sort subjects in a way that's connected to the outcome, creating a hidden bias before the experiment even starts.
04 // Start with the question and a measurable outcome
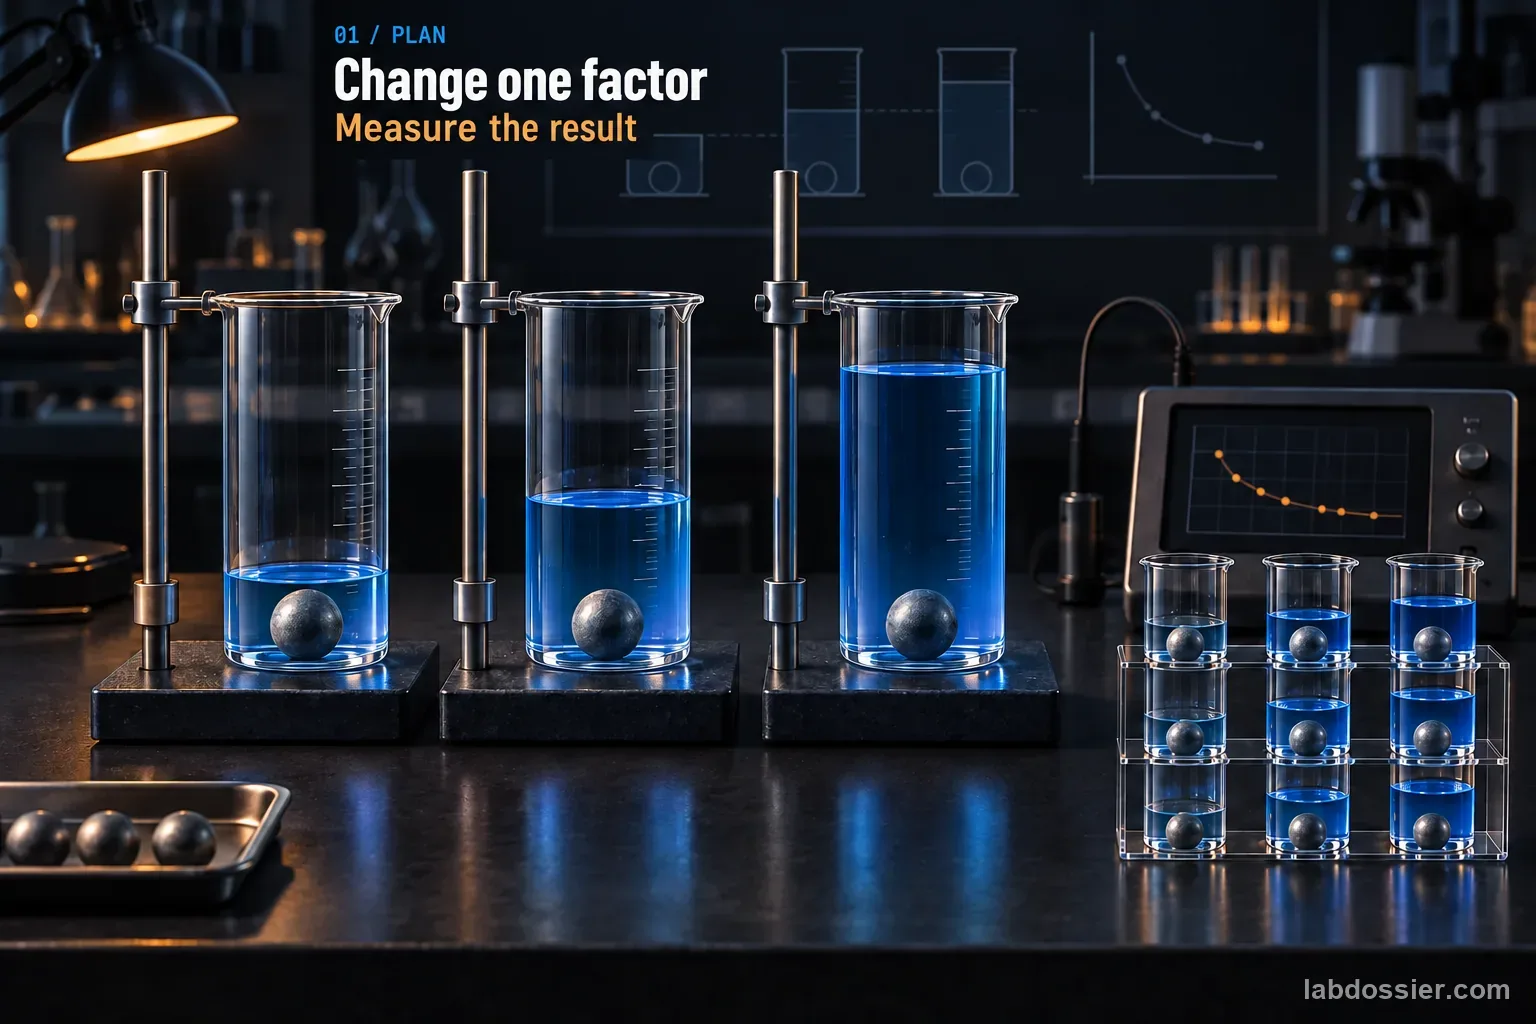
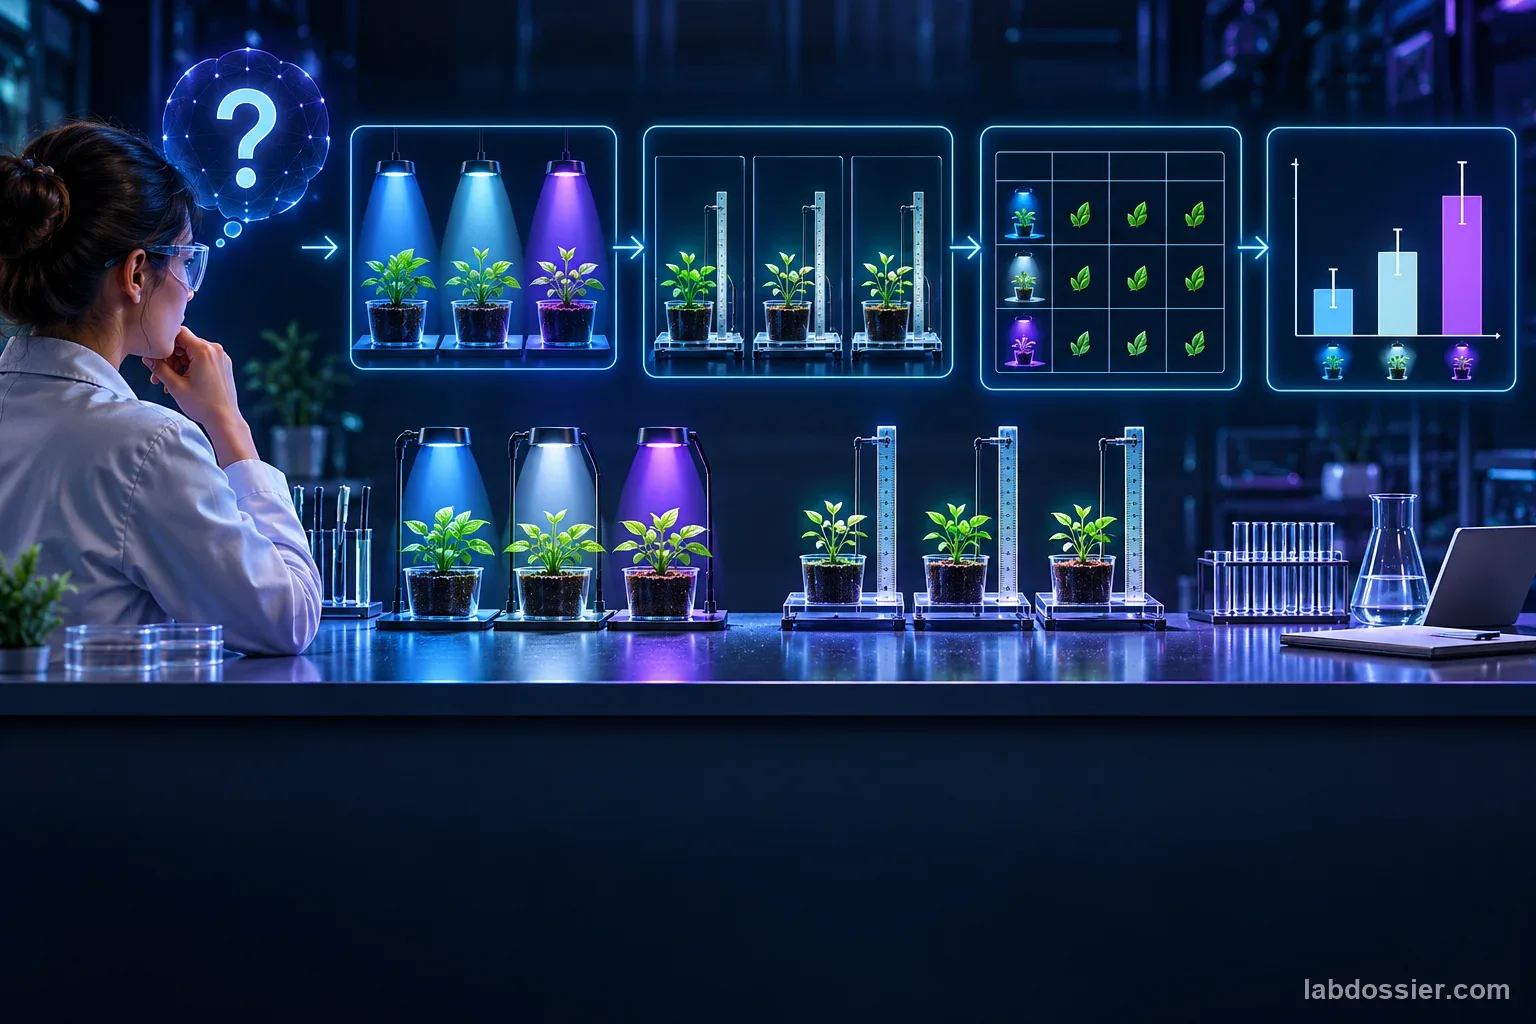
A useful design begins with a question narrow enough to test. Specify the population or material, the factor being compared, the outcome, and the time window. 'Does fertilizer help plants?' is broad; 'How does 0, 5, or 10 milliliters of this fertilizer per liter affect the average height of bean seedlings after three weeks?' gives a testable structure. The question should fit the available time, tools, safety rules, and sample size.
Choose the dependent measure before collecting data. Decide how it will be measured, with what instrument, at what time, and in what units. If several outcomes matter, designate the primary one and treat others as secondary observations. This reduces the temptation to select whichever measurement looks most favorable after the experiment is finished.
05 // Plan groups, controls, and replication
Identify the treatment levels and comparison condition. List controlled variables and explain how each will be matched. Decide how samples will be assigned to conditions; random assignment can reduce systematic placement bias when practical. Use repeated samples or repeated trials so natural variation is visible. A large number of measurements on one sample is not always equivalent to testing more independent samples.
Estimate a realistic sample size and plan what happens if a measurement fails. Record exclusion rules before looking at the outcome—for example, a sample may be excluded if the container breaks, not merely because its value differs from the prediction. Include a control group when it answers the question, but do not add a meaningless control simply because every worksheet shows one.
06 // Reduce bias in collection and analysis
Use the same equipment, measurement order, timing, and instructions across groups. Calibrate instruments where possible and keep labels clear. If observer expectations could influence a subjective score, use a defined rubric or have an assessor who does not know the treatment. Write the data table and graph plan before testing so measurements are not changed selectively later.
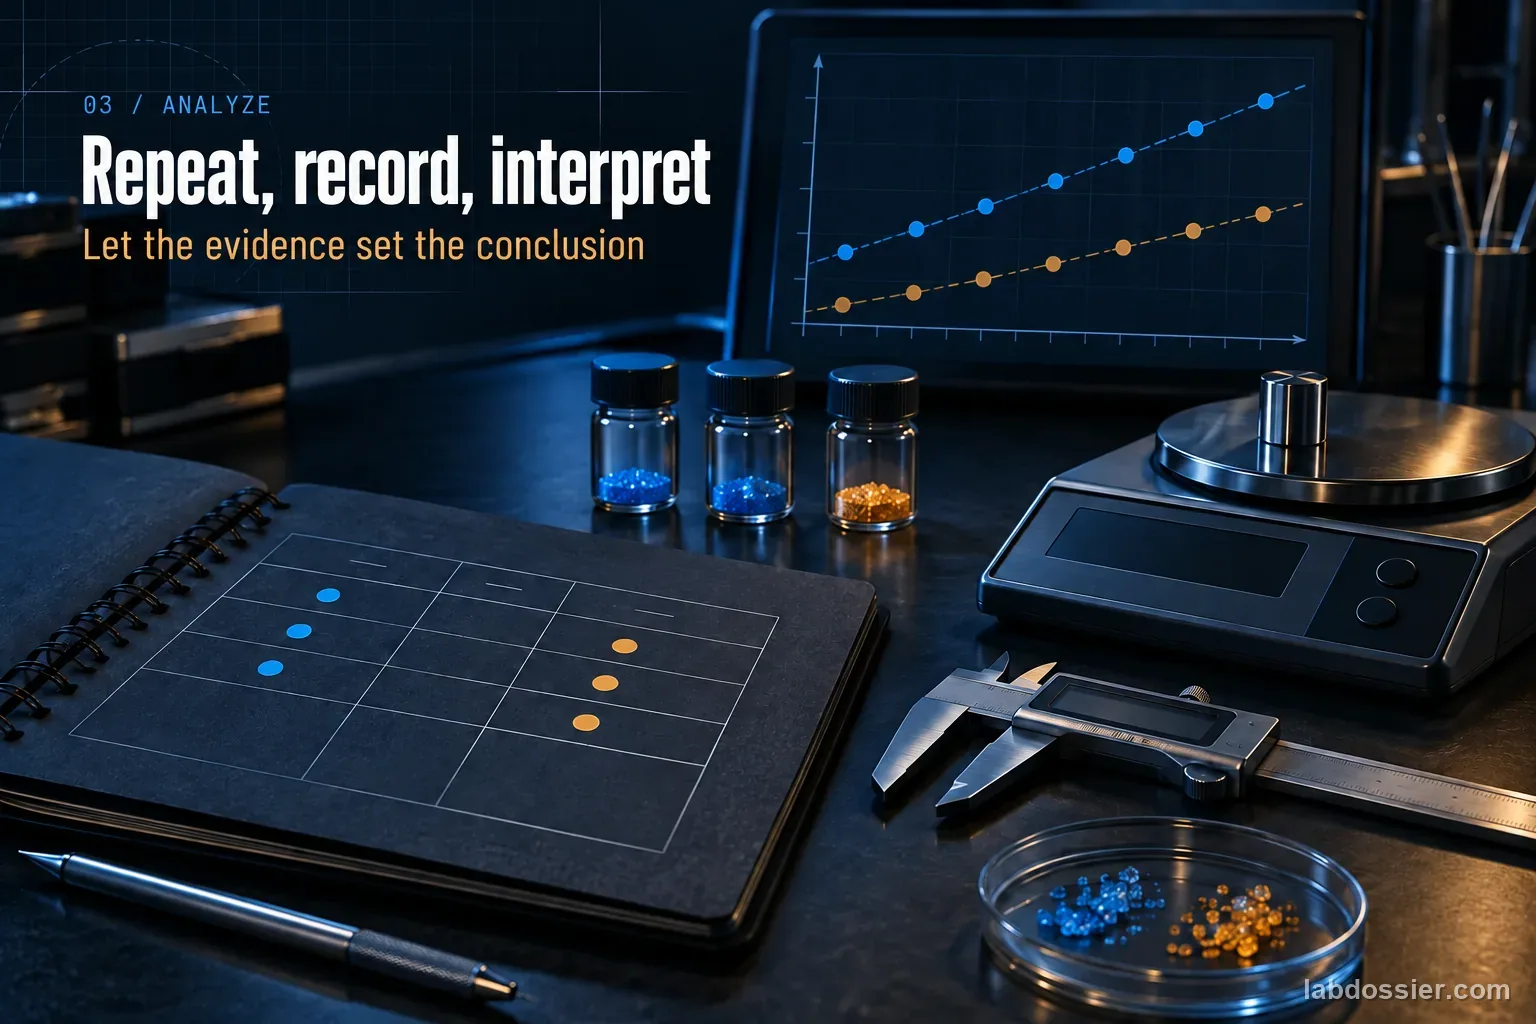
Choose an analysis that matches the design. A continuous independent variable may suit a scatterplot; categories may suit a bar chart; measurements over time may call for a line graph. Display individual points when the sample is small. Identify missing values and unusual trials, calculate summaries consistently, and avoid implying that a visible difference is meaningful without considering spread and measurement precision.
07 // Build safety and feasibility into the method
List hazards before the test and choose controls such as goggles, gloves, ventilation, adult handling, or substitution with a safer material. A design that is not safe or cannot be completed in the available period should be revised before materials are used. Consider waste, cleanup, accessibility, and whether participants or animals could be harmed. Real human or animal studies require formal oversight beyond a classroom worksheet.
Run a small pilot when time allows. A pilot can reveal that the measurement is too coarse, the procedure takes longer than expected, or the treatment levels do not produce a detectable difference. Record pilot changes and then begin the formal comparison with a stable method. A strong experiment is not the most complicated one; it is the simplest design that can answer the stated question credibly.
08 // Write decision rules before seeing results
Decide how a measurement will be summarized, which observations count as invalid for a procedural reason, and what evidence would distinguish the prediction from an alternative. Recording these rules before collection reduces the temptation to change the analysis after seeing which answer looks favorable. The rules should be practical, tied to the method, and written in the notebook.
A pilot can test whether instruments, timing, treatment levels, and sample size work as planned. Keep pilot data separate if the procedure changes substantially, and document what was revised. A well-planned small experiment is more informative than a complicated design whose measurements cannot answer its question.
09 // Make a plan that can distinguish a pattern from noise
Before collecting data, decide what counts as one experimental unit, how many independent units or trials you can reasonably test, and how you will handle a missed measurement. Repeating a reading on the same sample improves measurement confidence but is not the same as testing several independent samples. A plan should also specify the instrument, units, timing, and any rule for excluding a result, so those choices are not changed after seeing which outcome is convenient.
Sketch the planned table and graph before the experiment. Check that the independent variable has enough distinct levels to reveal a trend and that the dependent measure can actually respond on the timescale available. If materials or safety limits make the ideal design impossible, state the compromise and narrow the question. A carefully limited conclusion is more useful than a broad claim from a weak comparison.
10 // Questions people ask
What is the difference between experimental design and the scientific method?
The scientific method is the whole process, from asking a question through drawing a conclusion. Experimental design is specifically the planning stage within that process — deciding variables, controls, sample size, and how to avoid bias before any data is collected.
Why does sample size matter in experimental design?
A small sample size makes it hard to tell whether a result reflects a real pattern or just random chance. Testing more subjects, or running more trials, makes an unusual single result less likely to distort the overall conclusion.
What's the point of randomly assigning subjects to groups?
Random assignment helps spread out any unknown differences between subjects roughly evenly across groups, so those differences are less likely to become a hidden confounding variable that skews the result.