Science experiment data table
Open the Turn raw observations into a usable data table room
This article opens a matching guided lab. Follow the on-screen prompts, make a prediction, and connect the model result back to this topic.
01 // Build it before you collect data
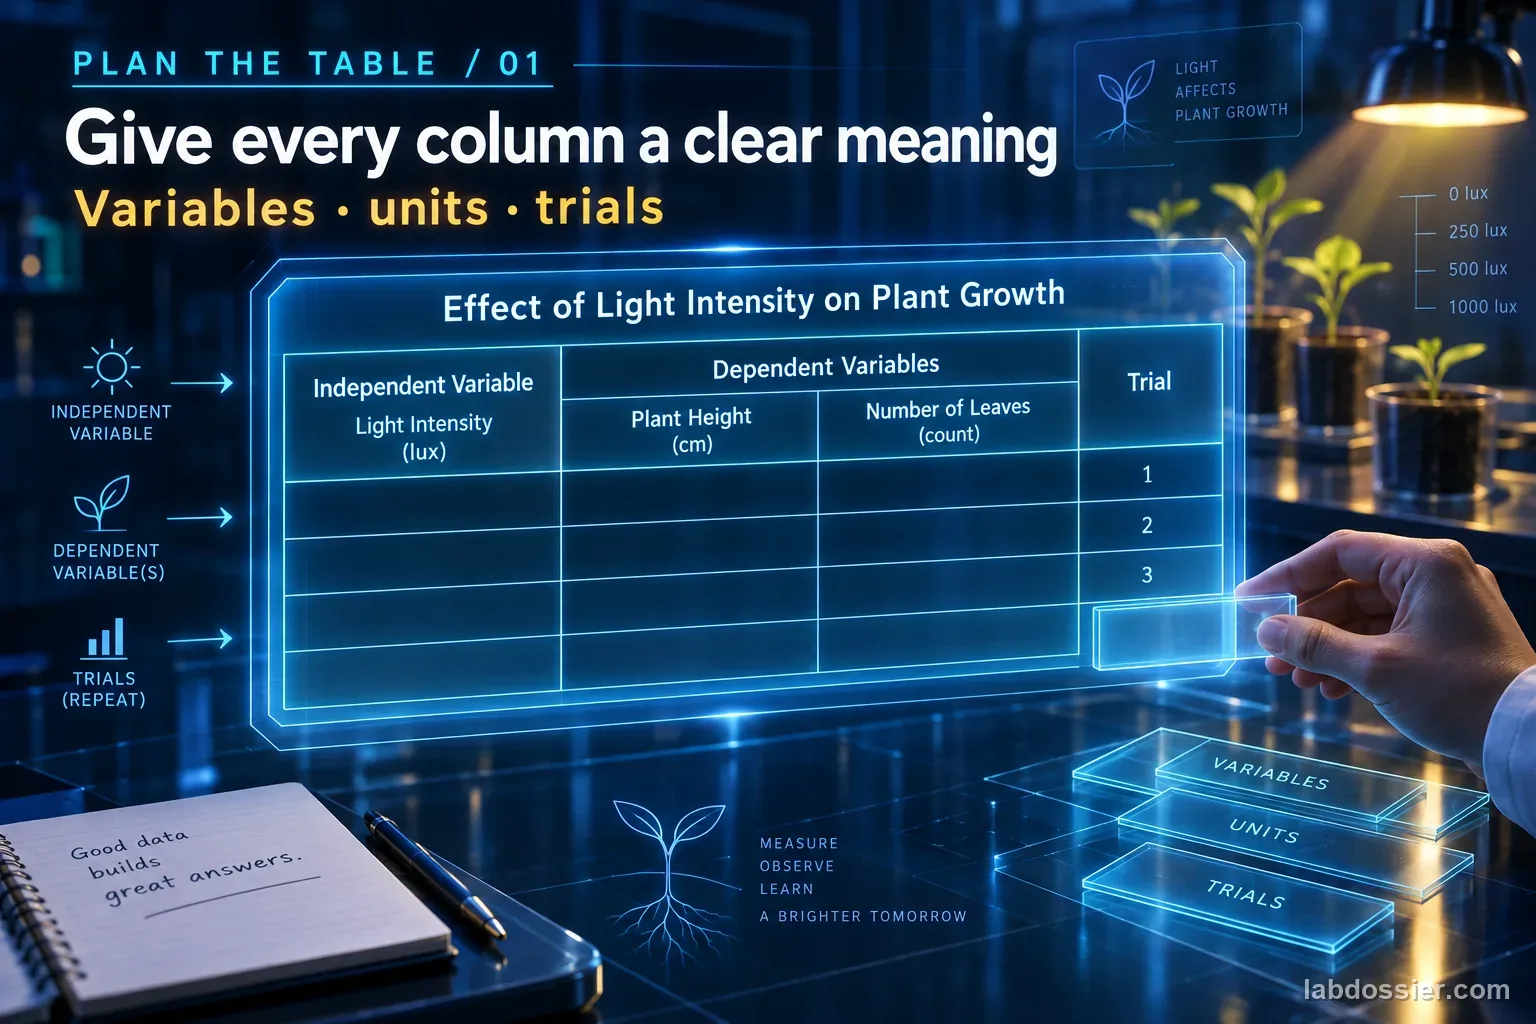
A data table works best when it's built before an experiment starts, not scribbled together afterward from scattered notes. Planning the table first forces you to think through exactly what you're changing, what you're measuring, and how many trials you'll run — which is really just the variables section of your experiment turned into a grid.
02 // How to set one up
1. Independent variable first
Put the thing you're changing on purpose in the leftmost column.
2. Units in the header, not every cell
Write the unit once in the column header, like "Mass (g)", instead of repeating it in every row.
3. One row per trial
Give every trial its own row so repeated measurements are easy to compare and average.
4. Leave room for calculated columns
Add columns for anything you'll calculate afterward, like an average or percent change, so the table stays in one place.
03 // Weak table vs. clear table
| Weak version | Clear version |
|---|---|
| Trial 1: 12g, Trial 2: 11.8g... | Rows and columns, one value per cell |
| "grams" repeated in every cell | "Mass (g)" written once, in the header |
| No title or units on the table | Title states exactly what's being measured |
| Independent variable buried mid-table | Independent variable in the leftmost column |
04 // Design the table before collecting data
Create a table with a descriptive title and columns for the independent variable, dependent measurement, trial number, and relevant conditions. Put units in the column headings rather than repeating them ambiguously in every cell. Arrange values in a logical order, such as ascending treatment level or chronological time.
Include enough rows for the planned trials and space for notes about anomalies. If several samples receive different treatments, label sample identities clearly. A table designed in advance reduces missing data and makes the collection procedure more consistent across groups.
05 // Separate raw observations from calculated summaries
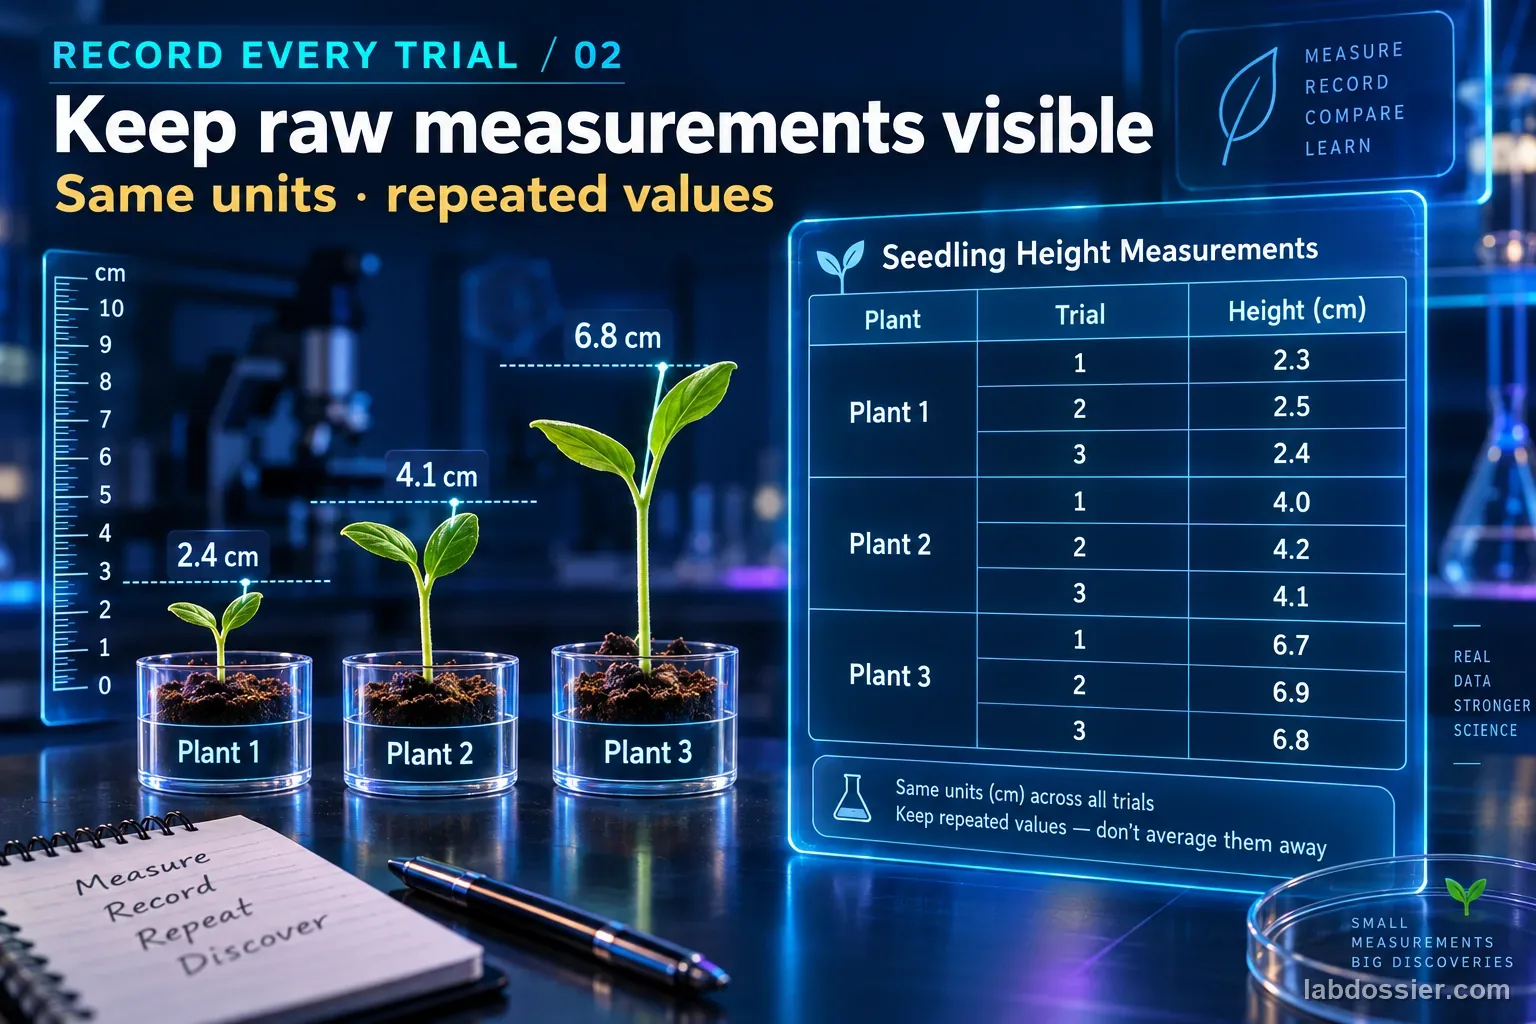
Record each trial as a separate observation before calculating a mean, rate, or percentage. Keep the raw values visible so another person can verify the calculation and inspect variation. Mark calculations in a separate column or table and identify the formula used. Never replace raw results with only a summary statistic.
Use consistent decimal places that reflect the measuring instrument, and record zero values differently from missing values. A blank cell should not silently mean zero. Use a note such as 'not measured' or an approved symbol, then explain the symbol. This prevents later readers from treating unavailable data as an observed absence.
06 // Make comparisons fair and readable
Keep units consistent within a column and convert values before comparison when necessary. Use clear headings such as 'Time (s)' instead of 'Time' alone. Align numerical values by decimal point when formatting allows, and avoid excessive decorative shading that makes cells difficult to read or print.
Include control conditions and all treatment levels relevant to the question. If the table becomes too wide, split it into related tables with repeated identifiers rather than removing labels. Note measurement conditions such as temperature or instrument where they could affect the result. A readable table helps identify patterns without implying that a pattern has already been statistically confirmed.
07 // Check and interpret the record
After collection, scan for impossible values, missing units, duplicated trial numbers, and transcription mistakes by comparing with the notebook. Correct errors transparently and retain the original where policy requires. Do not delete an outlier merely because it differs from the expected trend; investigate and document a defensible exclusion rule first.
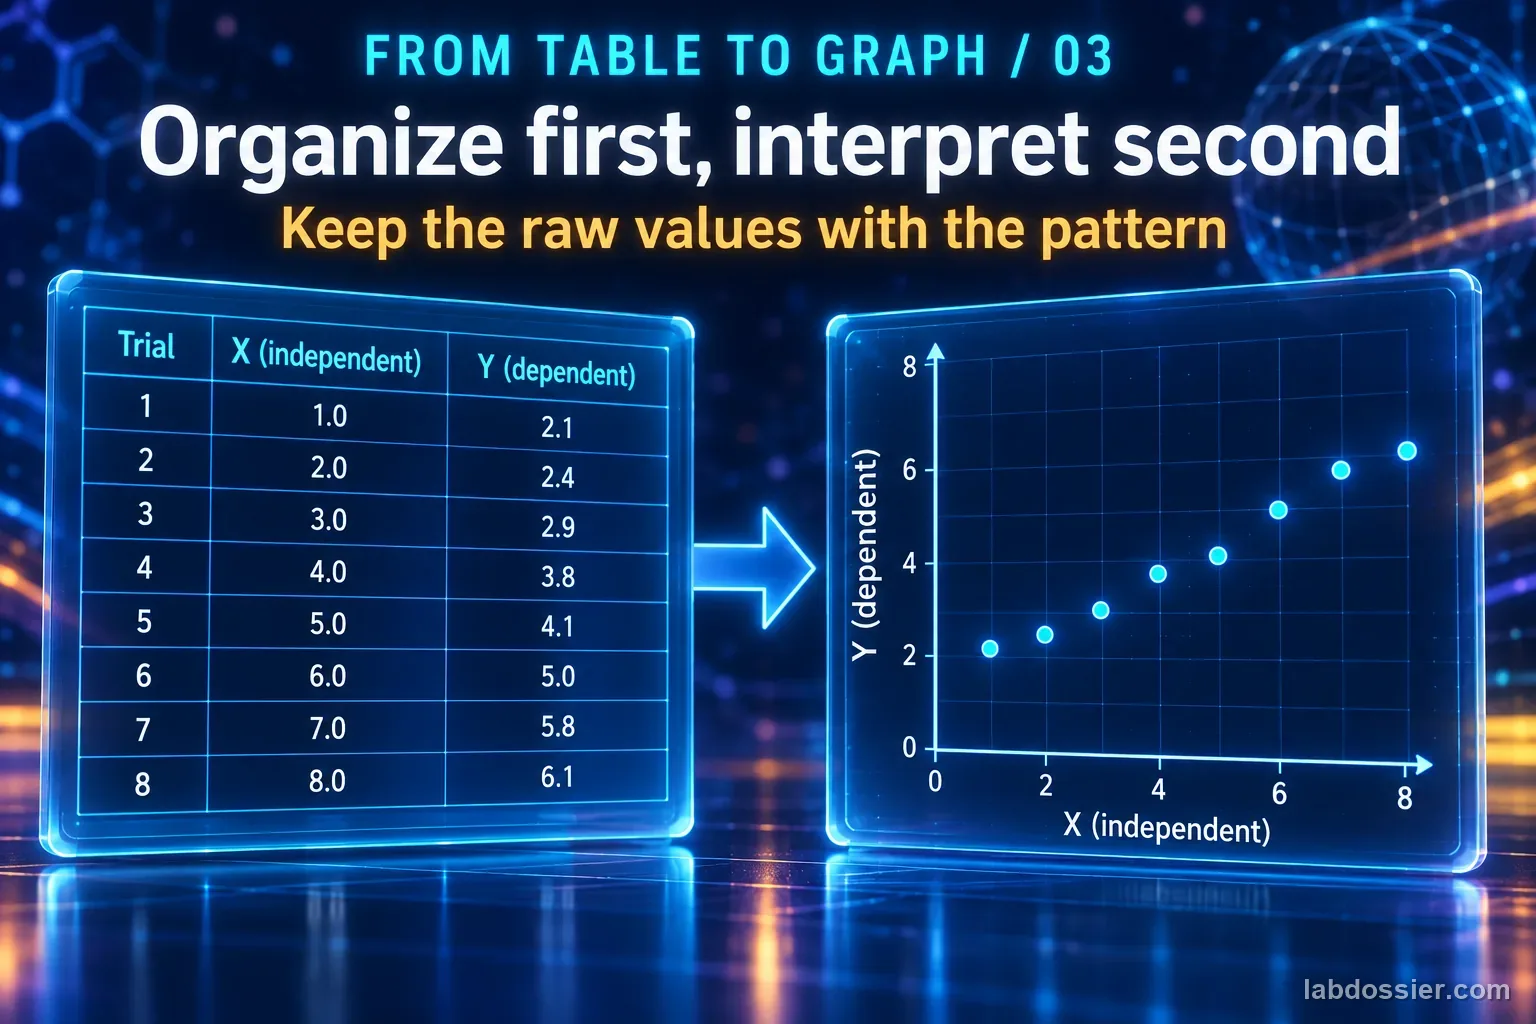
Use the table as the source for graphs and calculations, and verify that plotted values match it. In the discussion, cite specific rows or ranges and describe both the overall trend and the variability. A table organizes evidence; the explanation should connect it to the question while acknowledging limits in the sample size and measurement process.
08 // Keep repeated measurements traceable
Imagine testing how water temperature affects how quickly a sugar cube dissolves. A useful table could include water temperature (°C), trial number, time to dissolve (s), and a short note for unusual conditions. Put each trial on its own row, keep the temperature unit in its heading, and repeat the temperature on every trial row so the relationship remains clear when the table is sorted or copied.
Before testing, decide how to define 'dissolved' and how the timer will be started and stopped. Add a notes column for a cracked cube or a timer delay, but do not substitute a comment for the actual measurement. After collection, calculate a mean for each temperature in a separate summary table. Keep the original trial-level table unchanged so readers can inspect variability and check the summary.
09 // Example: organize a fair comparison
For repeated trials, define the row structure before beginning. One row per trial makes it easy to preserve individual observations and later group them by treatment. If the same sample is measured repeatedly over time, include both sample identifier and time point so readings are not mistakenly treated as independent samples. Repeat essential group labels when exporting or sorting data.
Check that every column contains one kind of information and one unit. Put notes in a dedicated column rather than mixing text such as 'spilled' into a numerical measurement column. When a value is missing, record the reason and use a consistent marker. These choices make later graphing and analysis less error-prone.
10 // Keep records usable after collection
A table should remain interpretable when copied out of the notebook. Repeat sample IDs and treatment labels on each row rather than relying on merged cells or color alone. Use a consistent date format, decimal precision, and missing-value code. A value of zero is an observation; a blank may mean not measured, lost, or accidentally omitted, so state which meaning applies.
Before graphing, compare row counts with the planned trials and check that every calculation points to the correct cells or measurements. Preserve a read-only copy of raw data when using a spreadsheet. These small practices prevent sorting or formula changes from silently attaching a result to the wrong sample.
11 // Questions people ask
Which variable goes in the first column of a data table?
The independent variable — the one you are deliberately changing — belongs in the leftmost column. The dependent variable, what you measure in response, goes in the columns to its right.
Where should units go in a data table?
Units belong once, in the column header, such as "Volume (mL)" — not repeated after every individual number in the column. This keeps the table easier to read and less cluttered.
Why build the data table before starting the experiment?
Planning the table first forces you to clearly define your variables and decide how many trials you'll run before you start collecting data, which prevents scrambling to organize scattered numbers after the fact.